The Problem That Forces Your Hand Your web application just hit a wall. Users are uploading images, and your server blocks for thirty seconds while ImageMagick churns through each resize operation. The browser times out. Users refresh. Your server dies under the load of duplicate requests. This is where most developers first encounter the need …
Month: March 2026
Start With What You Can Measure After fifteen years of watching developers struggle with slow queries, I’ve learned that database performance optimization begins with one fundamental truth: you cannot improve what you cannot measure. Most teams skip this step and jump straight into adding indexes or rewriting queries. That’s like trying to fix a car …
Understanding What You’ve Inherited You’ve just joined a team and inherited a codebase that feels like walking into someone else’s house in the dark. The previous developers made decisions that seem baffling now, but they had reasons. Your job isn’t to judge those decisions immediately. It’s to understand the system as it exists today. Start …
The Current State: We’ve Built Impressive Infrastructure After fifteen years of building distributed systems, I’ve watched observability evolve from afterthought to architecture cornerstone. We went from tail -f /var/log/messages to sophisticated platforms that ingest terabytes daily. Prometheus conquered metrics. The ELK stack democratized log analysis. OpenTelemetry standardized tracing. These tools are the nervous system of …
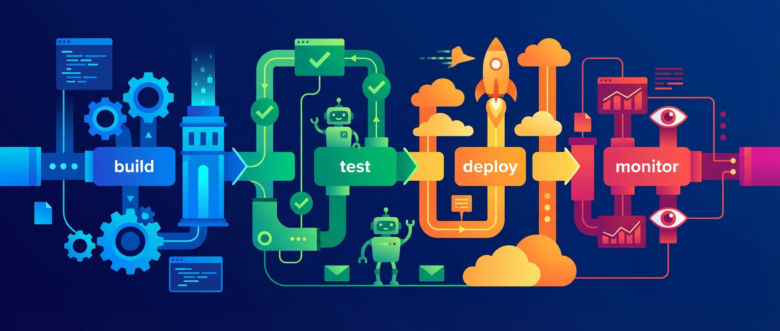
Start With Recovery, Not Prevention Most teams approach CI/CD pipeline design backwards. They obsess over preventing failures instead of planning for recovery. After watching dozens of production incidents unfold, the pattern becomes clear: the teams that sleep well at night aren’t the ones with perfect pipelines. They’re the ones whose pipelines fail gracefully and recover …
The Problem With Debt Metaphors Technical debt isn’t actually debt. I’ve spent fifteen years watching teams torture themselves with financial metaphors that don’t map to software reality. Real debt has fixed payment schedules, interest rates, and clear payoff dates. Technical debt is more like entropy. It accumulates. It spreads. It compounds in ways that would …